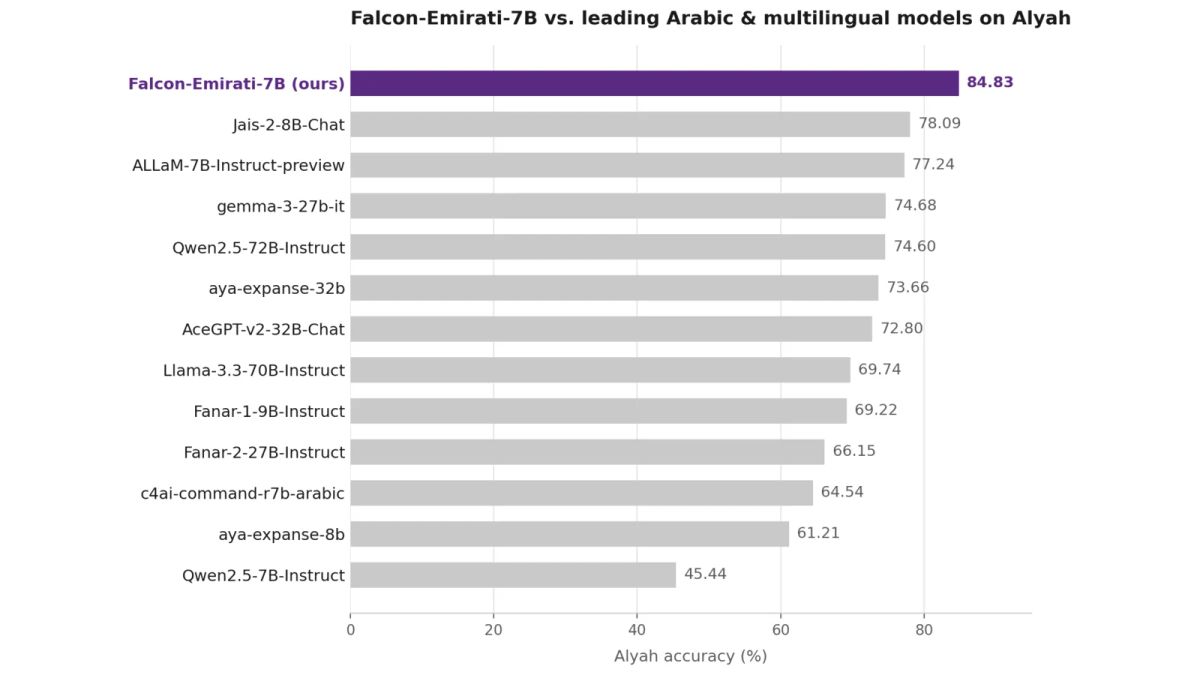
The Technology Innovation Institute has announced Falcon-Emirati-7B, a language model adapted for Emirati Arabic and the cultural context behind it. In its Hugging Face post, TII reports 84.83% accuracy on Alyah, a benchmark of Emirati dialect and cultural knowledge. Readers can try the model on TII’s Falcon Chat platform.
The target is more specific than general Arabic fluency. Modern Standard Arabic is common in formal writing, while Emirati conversation uses local vocabulary, idioms and cultural references. TII built the model to understand those differences and answer in Emirati Arabic.
A 7B Arabic base with local training data
Falcon-Emirati uses the 7-billion-parameter version of Falcon-H1-Arabic. That family combines Mamba state space models with Transformer attention and already has training in Modern Standard Arabic and several Arabic dialects. TII says it chose 7B to balance dialect quality with training and inference costs.
The adaptation draws on Emirati websites and forums, Modern Standard Arabic material about Emirati culture, and synthetic dialect text. TII constrained the synthetic data with Emirati glossaries and grammar rules. The cultural material covers subjects such as heritage, customs and social norms, giving the model context alongside dialect vocabulary.
TII says it tested different data mixtures and training stages, using automatic scores and native-speaker reviews to judge progress. Native speakers assessed naturalness, tone and cultural fit.
Recognizing an answer and producing the dialect
Alyah contains 1,173 multiple-choice questions collected from native Emirati speakers. Its subjects include greetings, figurative language, heritage and poetry. TII’s chart puts Falcon-Emirati at 84.83%, ahead of Jais-2-8B-Chat at 78.09% and ALLaM-7B-Instruct-preview at 77.24%.
TII also asked models to generate answers to the same questions, then used an LLM judge to score correctness and dialect fidelity separately. Falcon-Emirati received a partial-credit dialect score of 0.52, compared with 0.05 for ALLaM and 0.03 for gemma-3-27b-it. TII attributes the difference to competing models often answering in Modern Standard Arabic.
A separate cultural test used 283 UAE scenarios from ArabCulture-Dialogue. Averaged across language varieties and location settings, Falcon-Emirati scored 85.57%, compared with ALLaM’s 83.39%. These are TII’s reported evaluations.
The model is available through Falcon Chat. TII warns that rare expressions and highly local references can still cause errors, and recommends use-case testing before sensitive or official use.
Sources
- Technology Innovation Institute: Falcon-Emirati: When an LLM Learns the Dialect, the Culture, and the Nuance. Announcement, evaluation results and lead chart. Image credit: Technology Innovation Institute.