NVIDIA AI News
AWS and NVIDIA plan 2 million more GPUs for agentic AI
AWS and NVIDIA say they will deploy 2 million additional NVIDIA GPUs across AWS in 2027-2028 and deepen the stack around agents, robotics, open models, and government AI.

By The AI Feed Desk
NVIDIA AVO reaches 100% on ARC-AGI-3 public set
NVIDIA says its AVO agent architecture completed all 183 public ARC-AGI-3 levels, showing how persistent memory and supervision change agent benchmarks.
By The AI Feed Desk
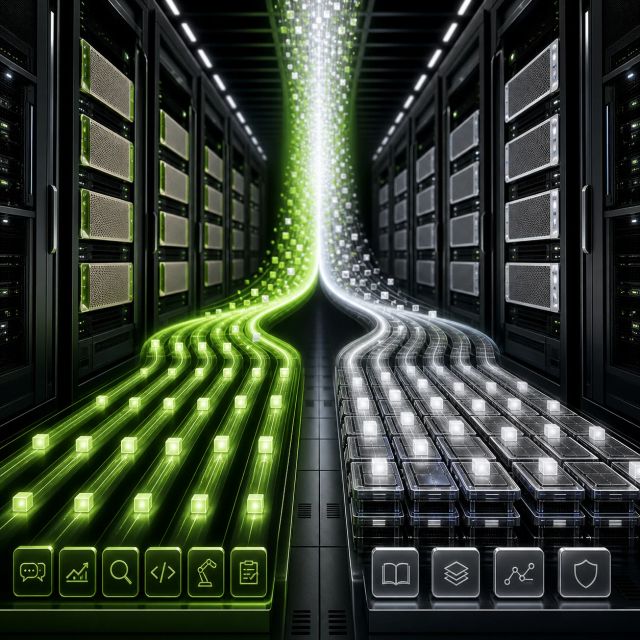
NVIDIA extends Vera Rubin with Groq 3 LPX for agentic inference
NVIDIA says Groq 3 LPX is in full production as a Vera Rubin decode accelerator, shifting agent infrastructure toward rack-scale token generation economics.
By The AI Feed Desk
Firebird opens NVIDIA-backed AI factory in Armenia
Firebird opened an NVIDIA-backed AI factory in Armenia and plans more than 70,000 Rubin and Blackwell GPUs with 300 MW of capacity by 2027.
By The AI Feed Desk
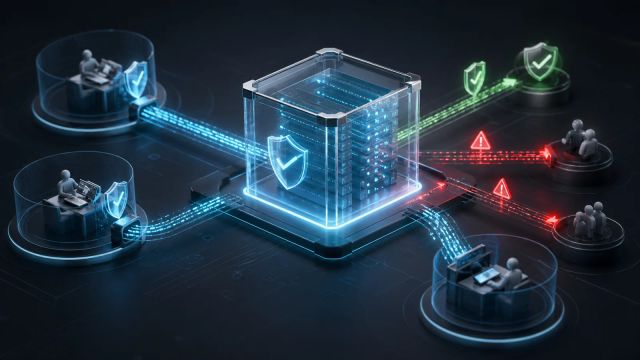
Open Secure AI Alliance proposes SAFE guidelines for agent security findings
The Open Secure AI Alliance proposed SAFE guidelines for sharing agentic AI cybersecurity findings as Black Hat USA opened.
By The AI Feed Desk
NVIDIA makes Alpamayo 2 Super available for commercial robotaxi development
NVIDIA released Alpamayo 2 Super for commercial autonomous-vehicle development, tying an open 32B reasoning model to its simulation and validation stack.
By The AI Feed Desk
NVIDIA gives Safe Superintelligence a 10x compute path
NVIDIA and Safe Superintelligence announced a long-term partnership that includes NVIDIA investment and access to Vera Rubin systems.
By The AI Feed Desk
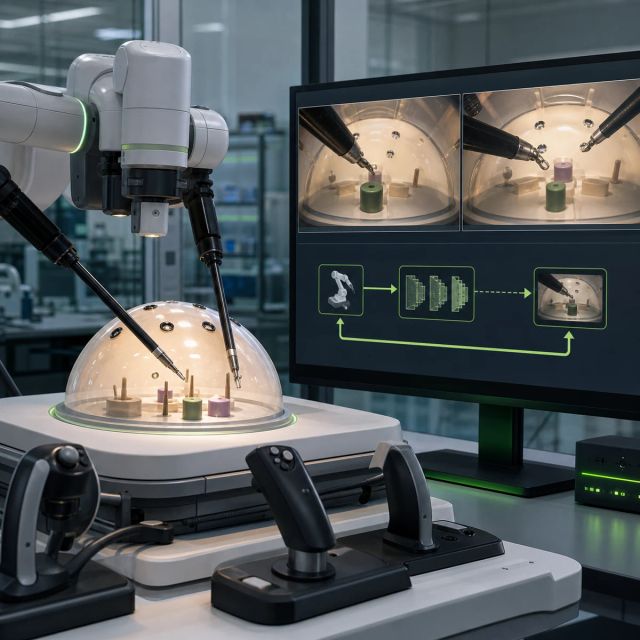
NVIDIA Cosmos-H-Dreams turns surgical world models into a real-time simulator
NVIDIA published Cosmos-H-Dreams, a real-time action-conditioned generative simulator for surgical robotics built from Cosmos-H-Surgical-Simulator.
By The AI Feed Desk
NVIDIA and Anthropic split over open-weight AI safety
NVIDIA launched the Open Secure AI Alliance while Anthropic argued against blanket open-weight bans and for targeted AI safety controls.
By The AI Feed Desk
NVIDIA frames Vera Rubin around agentic post-training economics
NVIDIA says Vera Rubin is built for continuous post-training loops and can train the largest models with one-fourth the GPUs of Blackwell.
By The AI Feed Desk
NVIDIA uses Japan to package physical AI as a full-stack ecosystem
NVIDIA's July 15 Japan ecosystem update ties RTX Spark, robotics, manufacturing, and local partners into a physical AI stack.
By The AI Feed Desk
NVIDIA and Hugging Face publish open data for agents
NVIDIA and Hugging Face published a Nemotron data package for agents, including open pretraining data, post-training samples, an interactive Prompt Atlas, and synthetic persona datasets.
By The AI Feed Desk
NVIDIA frames U.S. AI buildout as a 43-state supply chain
NVIDIA says its U.S. partner network spans 43 states and plans up to $500 billion of American-built AI infrastructure with semiconductor, system, power, and cloud partners.
By The AI Feed Desk
NVIDIA turns AI cloud capacity into a revenue-sharing model
NVIDIA's new AI cloud model pairs revenue sharing with credit support, giving emerging cloud providers a way to finance AI factories while tying NVIDIA to downstream token demand.
By The AI Feed Desk
Claude reaches Microsoft Foundry with Azure governance and GB300 compute
Anthropic made Claude generally available in Microsoft Foundry, while NVIDIA framed the Azure deployment as a GB300 Blackwell Ultra agent platform.
By The AI Feed Desk
NVIDIA and Palantir put Nemotron open models inside air-gapped government AI
NVIDIA says Palantir is using Nemotron open models in isolated environments for U.S. government agencies and critical infrastructure operators.
By The AI Feed Desk
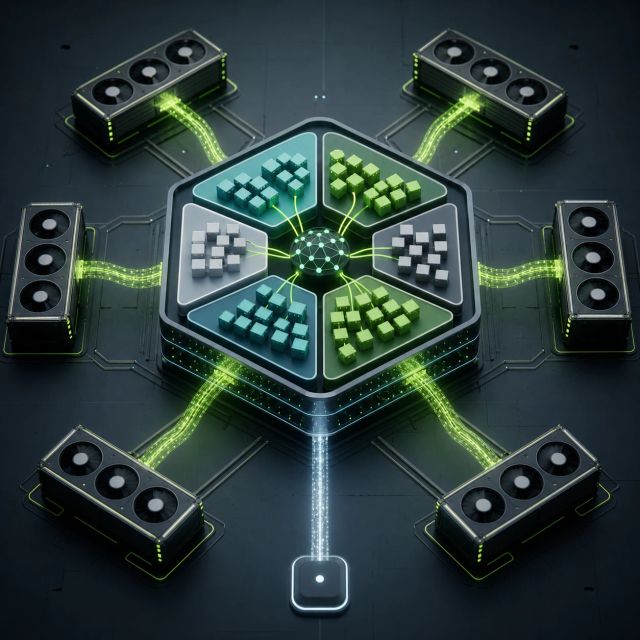
NVIDIA NeMo AutoModel makes MoE fine-tuning a one-import upgrade
NVIDIA's Hugging Face article shows NeMo AutoModel wrapping expert parallelism and custom kernels behind the familiar Transformers loading path for MoE fine-tuning.
By The AI Feed Desk