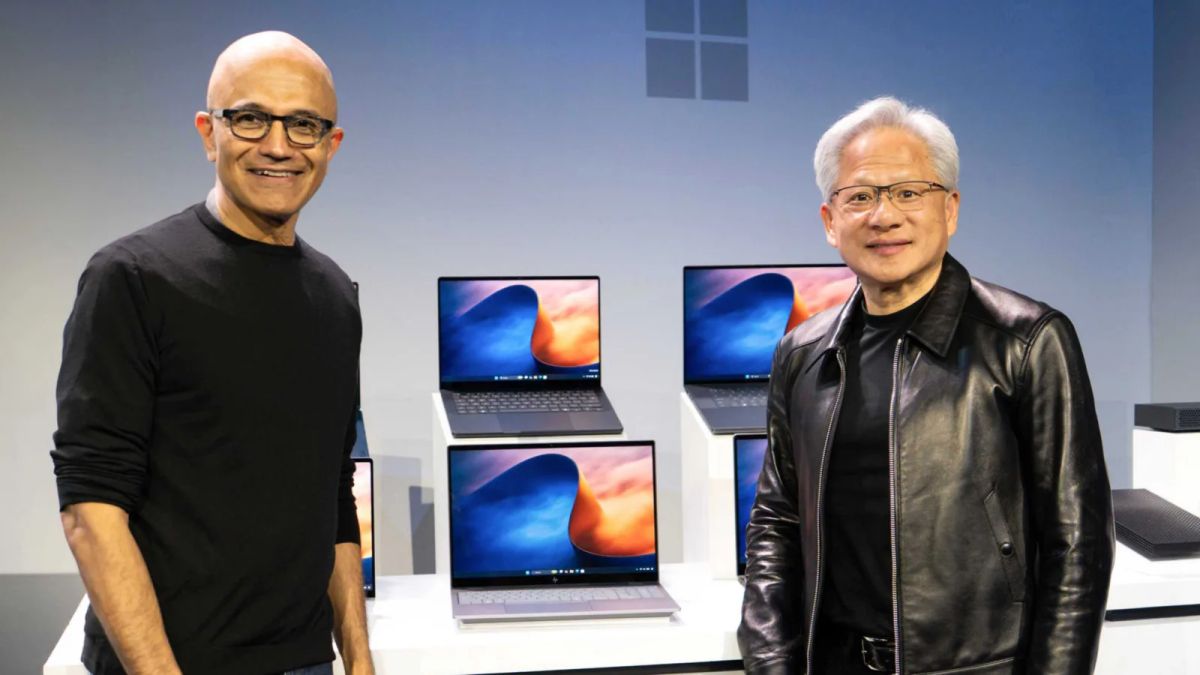
Satya Nadella and Jensen Huang standing beside a display of Windows laptops
+ AI News

Microsoft and Nvidia launch RTX Spark PCs, with laptops priced up to $7,000

RTX Spark laptops start at $2,599. The $7,000 model is an Asus, while the buying case against a MacBook Pro depends on memory and the software you run.

Microsoft and Nvidia presented RTX Spark Windows PCs on October 7, aimed at developers running AI locally and creators. The first laptops start at $2,599, according to The Verge. The roughly $7,000 configuration belongs to Asus’ ProArt P16. TechCrunch reports Surface Laptop Ultra configurations reaching $5,900.

The distinction matters when shopping. RTX Spark names a hardware family across several makers, and its starting price buys far less memory than the maximum Nvidia advertises.

What the prices buy

The Verge reports these configurations, with the Surface’s full option list still unclear at publication.

Laptop configurationReported priceMemory and storage
Entry RTX Spark laptop, 18-core CPUStarts at $2,59924GB unified memory, 512GB storage
Surface Laptop Ultra listed at Best Buy$3,999.9948GB memory
Asus ProArt P16, 20-core CPU$6,999.99128GB unified memory, 2TB storage

The same report places the entry configuration close in price to a 14-inch M5 Pro MacBook Pro, which includes 1TB of storage. It says a fully configured 16-inch M5 Max MacBook Pro can approach $10,000. Those are price comparisons across different configurations. The sources provide no shared performance tests.

Hardware for local models, Windows for agents

Nvidia’s announcement lists a Blackwell RTX GPU with up to 6,144 cores, a Grace CPU with up to 20 cores, and up to 128GB of unified memory. Its advertised one petaflop measures FP4 AI compute. RTX Spark supports CUDA, plus AV1 and 4:2:2 video processing.

Nvidia says laptop preorders opened October 7, with availability October 16. Compact desktops follow in November.

At the event, Satya Nadella argued for a secure desktop where agents can execute. Jensen Huang described an agent on a person’s computer as a personal assistant. Microsoft announced general availability of Microsoft Execution Containers, which it says let agents run persistently in the background under Windows control.

Sources

The AI Feed Desk

The AI Feed Desk

Editorial desk

The AI Feed Desk tracks AI provider updates, model releases, agent tooling, and enterprise adoption, turning fast-moving announcements into source-linked context for builders and operators.

Noticed a typo, incorrect information, or translation error?

Tell us so we can fix it.

Help Improve This Article

Related Articles

Satya Nadella and Jensen Huang beside a display of Windows laptops

How Microsoft is changing Windows for Nvidia's RTX Spark laptops

Microsoft is tuning Windows for RTX Spark's local agents, shared memory and Arm apps. Copilot Plus features and some game support arrive later.

The AI Feed Desk

By The AI Feed Desk

NVIDIA's official COMPUTEX article card for RTX Spark and local AI agents

NVIDIA announces RTX Spark PCs for local AI agents

RTX Spark puts 1 petaflop of AI performance and up to 128GB of unified memory into Windows PCs designed for local agents.

The AI Feed Desk

By The AI Feed Desk

A pull request review panel connects to Jira cards and a guarded plugin marketplace

GitHub turns Copilot governance into a code-review and Jira story

GitHub's June 25 Copilot updates pair cheaper code-review analysis with Jira agent visibility and stricter controls over plugin marketplaces.

The AI Feed Desk

By The AI Feed Desk

A Copilot routing panel sends developer tasks either to automatic model selection or to private model providers

GitHub makes Copilot routing more automatic while opening BYOK in the app

GitHub's latest Copilot changes push Free and Student users toward automatic model routing while giving Copilot app users bring-your-own-key model providers.

The AI Feed Desk

By The AI Feed Desk

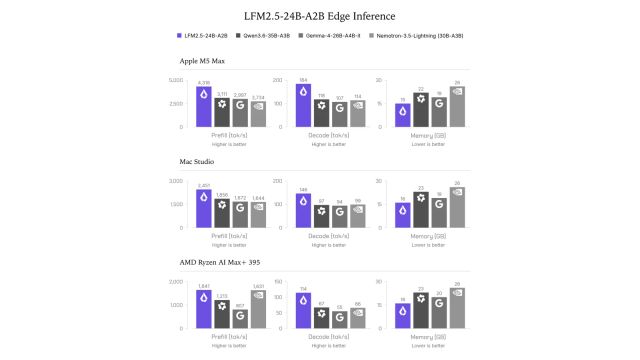
Bar charts comparing LFM2.5-24B-A2B prompt processing, token generation and memory use against three other models on Apple and AMD hardware

Liquid AI releases LFM2.5-24B-A2B for fast on-device agents

Liquid AI's 24B mixture-of-experts model uses 2B active parameters for local reasoning and tool calls. Its agent workflows differ from d1's single-pass decisions.

The AI Feed Desk

By The AI Feed Desk