Local AI
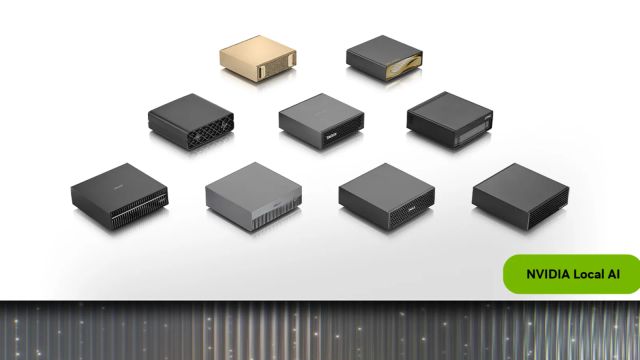
Nvidia's DGX Spark gets a 64GB unified memory version this month
Nvidia's 64GB DGX Spark arrives October 23 from partner manufacturers, starting at $4,999. Its 100-billion-parameter claim needs a closer memory-budget check.

By The AI Feed Desk
Liquid AI releases LFM2.5-2.6B for on-device agents
Liquid AI released LFM2.5-2.6B, a small local model trained for tool calling, multi-step workflows, and 128K-token context.
By The AI Feed Desk
Program-as-Weights turns fuzzy functions into local adapters
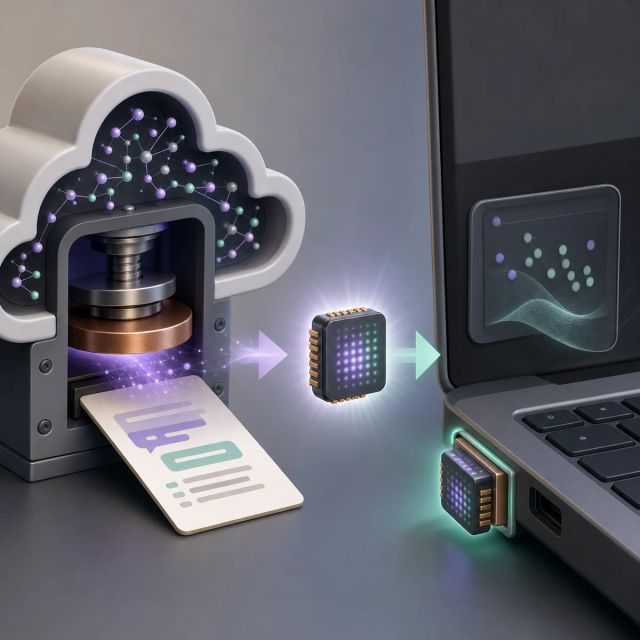
A new arXiv paper proposes compiling natural-language fuzzy functions into small local adapters, shifting some LLM work from repeated API calls to reusable artifacts.
By The AI Feed Desk
Google releases DiffusionGemma for faster local text generation
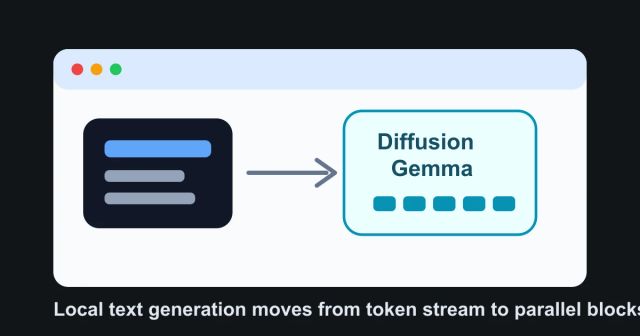
Google's DiffusionGemma is an experimental open text-diffusion model that generates blocks of text in parallel for lower-latency local workflows.
By The AI Feed Desk
Google releases Gemma 4 QAT checkpoints for local models
Google's Gemma 4 QAT release adds Q4_0 and mobile checkpoints, cutting Gemma 4 E2B to a 1GB memory footprint for local and on-device use.
By The AI Feed Desk
Google releases Gemma 4 12B for local multimodal agents
Google's Gemma 4 12B is a 12B-parameter open model for local multimodal work, with 16GB memory guidance, native audio inputs, and a 256K-token context window.
By The AI Feed Desk
NVIDIA announces RTX Spark PCs for local AI agents
RTX Spark puts 1 petaflop of AI performance and up to 128GB of unified memory into Windows PCs designed for local agents.
By The AI Feed Desk