Transformers
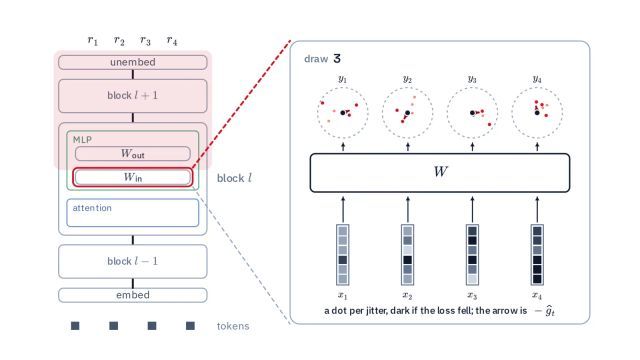
NVIDIA NeMo AutoModel makes MoE fine-tuning a one-import upgrade
NVIDIA's Hugging Face article shows NeMo AutoModel wrapping expert parallelism and custom kernels behind the familiar Transformers loading path for MoE fine-tuning.

By The AI Feed Desk
Hugging Face measures whether tools are agent-friendly
Hugging Face's agent-focused benchmark tests whether software changes help coding agents finish tasks with fewer errors, tokens, and detours.
By The AI Feed Desk