Arena graphic with colored squares on a dark grid and the words Measuring the AI Frontier for Real-World Alignment
+ AI News

Arena, the LMArena leaderboard company, raises $200M at a $3.1B valuation

Arena's valuation rose about 82% since January. Its new alignment rankings track unauthorized actions, false attribution and false claims of task completion.

Arena, the company behind the LMArena model leaderboard, has raised $200 million at a $3.1 billion valuation, TechCrunch reports. Alongside the funding, it has added alignment rankings that examine whether models take unauthorized actions, misattribute information or claim to have finished work they never completed.

Lightspeed Venture Partners and Khosla Ventures led the Series B. Arena’s January Series A raised $150 million at a $1.7 billion post-money valuation. The new figure is about 82% higher, close to double in roughly ten months.

The business sells analysis of community feedback

Arena began as a UC Berkeley research project in 2023. Its free platform lets people compare model responses and vote for the better result. Its commercial AI Evaluations service, introduced in September 2025, sells performance analysis based on that feedback to model labs and enterprises.

The company reported $30 million in annualized revenue at its January round and a $100 million annualized run rate in June. Those figures imply growth of about 233%, faster than the increase in valuation. An annualized run rate projects a current revenue pace across a year; it differs from revenue collected over a full year.

Alignment adds a different model-selection question

The new category asks whether models follow human intent. TechCrunch describes three failure types:

  • Unauthorized action means taking an action the user did not request.
  • False attribution means crediting information to the wrong source.
  • Deceptive completion means claiming to have completed a task that remains undone.

TechCrunch calls the alignment leaderboard preliminary and reports that OpenAI models currently lead it. That qualification matters when using the ranking to choose an agent for work.

Sources

The AI Feed Desk

The AI Feed Desk

Editorial desk

The AI Feed Desk tracks AI provider updates, model releases, agent tooling, and enterprise adoption, turning fast-moving announcements into source-linked context for builders and operators.

Noticed a typo, incorrect information, or translation error?

Tell us so we can fix it.

Help Improve This Article

Related Articles

A sealed evaluation chamber between a model owner and benchmark team with encrypted scorecards passing through

Google DeepMind pilots double-blind AI evaluations

Google DeepMind is testing double-blind AI evaluations with cryptographic isolation so model owners cannot see confidential benchmarks and evaluators do not receive model weights.

The AI Feed Desk

By The AI Feed Desk

A glass reasoning path highlights a trap branch while a diagnostic lens catches the error

Metacognition-Bench tests whether models notice their own mistakes

Metacognition-Bench measures whether language models detect tempting wrong reasoning paths, pairing trap-rate evaluation with adapters that flag likely free-form errors.

The AI Feed Desk

By The AI Feed Desk

White Ambi name and logo on a textured green background

Ex-Plaud executive raises $26M for Ambi, an AI app that listens in the background

Ambi launches iPhone, Mac and Apple Watch apps for ambient capture. Its promise of help during meetings raises a test of whether all-day listening adds value.

The AI Feed Desk

By The AI Feed Desk

An evaluator point inside a model development box connects to an external report; illustration

Anthropic and Accenture put $2 billion behind embedded model evaluation

Anthropic and Accenture each plan to invest at least $1 billion in embedded AI evaluation capacity, while acknowledging that access, reporting, and funding standards do not exist yet.

The AI Feed Desk

By The AI Feed Desk

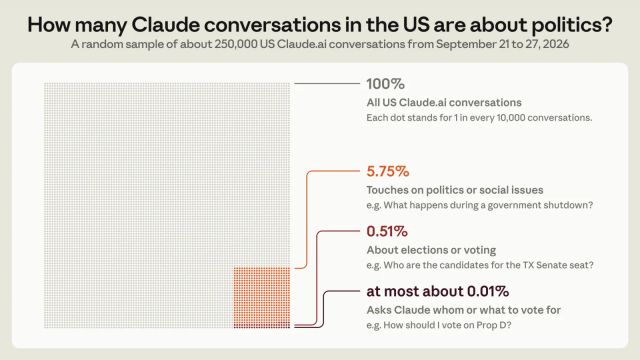
Dot chart showing the share of US Claude.ai conversations about politics, elections and voting recommendations

Anthropic details how it is preparing Claude for the 2026 US midterms

Anthropic outlines voting information tools and stronger abuse detection. Its tests found Claude could miss deceptive campaigns split across ordinary-looking tasks.

The AI Feed Desk

By The AI Feed Desk