NVIDIA and Hugging Face published a “Data for Agents” package arguing that agent progress depends on inspectable workflow data, synthetic data, and open methods, not only open model weights.
The July 8 article frames the problem plainly: agents need to recover from broken API calls, unfamiliar workflows, tool-use failures, retrieval errors, safety boundaries, user simulation, and multi-step reasoning. NVIDIA’s answer is to expose more of the data layer behind Nemotron.
The numbers are large. NVIDIA says Nemotron open data includes more than 10 trillion pretraining tokens and millions of post-training samples across domains and data shapes. The post also points to an interactive Nemotron Post-Training v3 Prompt Atlas, where users can explore sampled prompts by dataset, pipeline stage, domain, and tool use.
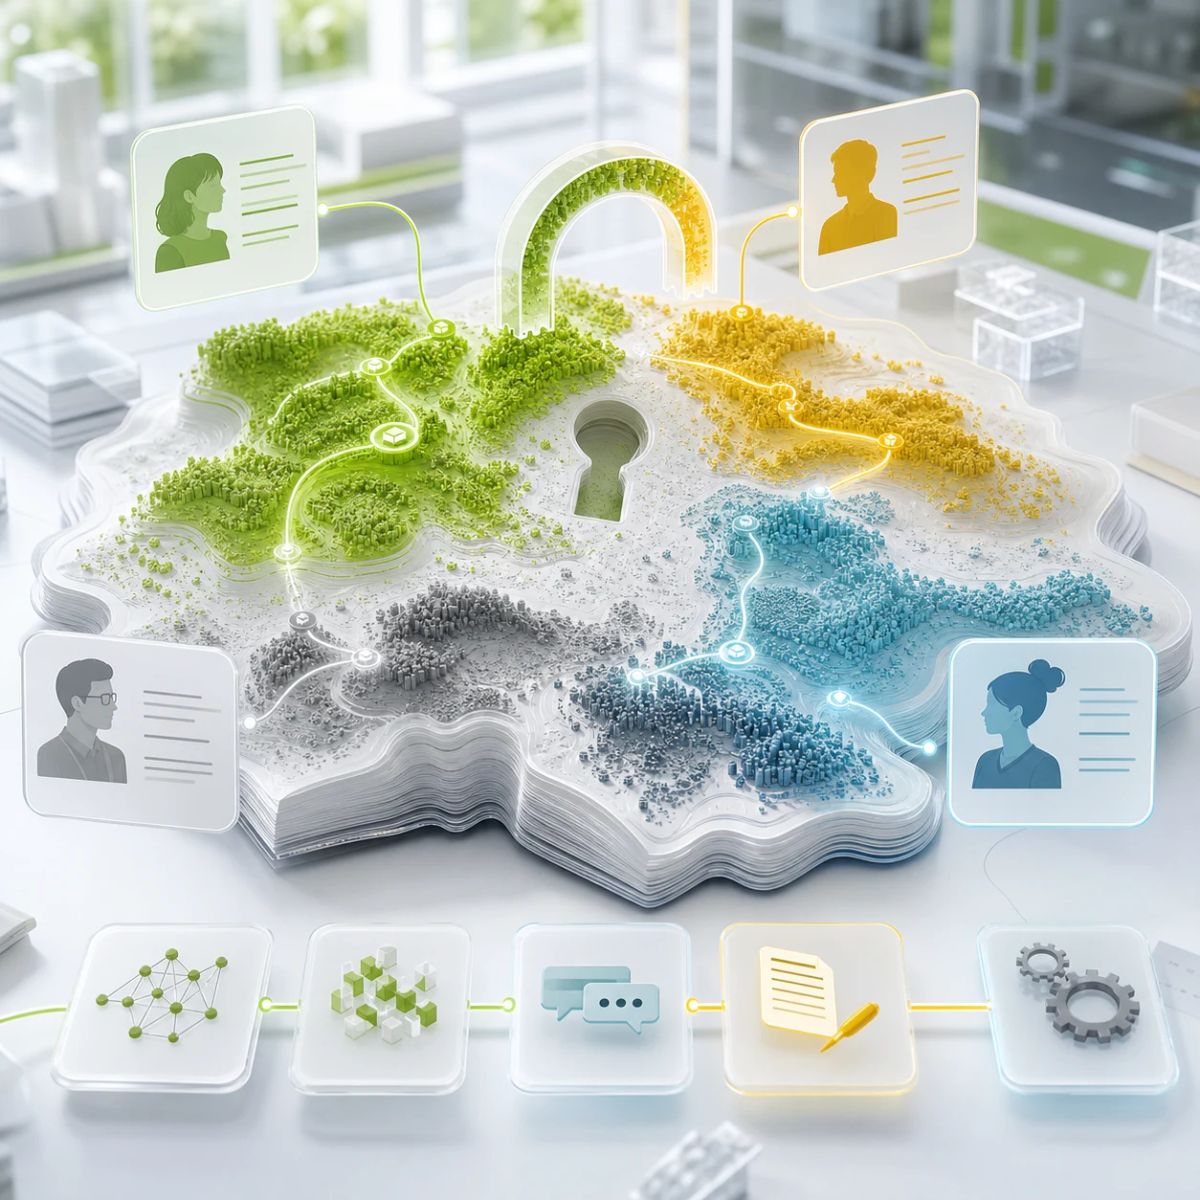
The package also highlights synthetic personas. NVIDIA says the Nemotron-Personas collection has launched its tenth country and now represents more than 2.4 billion people through region-specific synthetic persona datasets.
Agent data is different from chat data
Training a chatbot on text is not the same as training an agent to survive real work.
An agent has to call tools, notice failures, recover, ask for missing inputs, retrieve the right source, and avoid doing dangerous things just because the next step is easy. That behavior depends on examples of workflows, tool traces, edge cases, failure recovery, and evaluation criteria.
NVIDIA’s Prompt Atlas is useful because it makes part of that mixture visible. Instead of treating post-training data as an opaque table, the atlas lets people inspect clusters of semantically similar prompts and compare domains such as coding, safety, math, and agentic behavior.
That does not make the data perfect. It makes the curation choices easier to question. For open model ecosystems, that is the point: if model behavior is shaped by training data, the training data needs to be inspectable enough for builders to understand what kind of agent they are inheriting.
Synthetic data is a trust strategy, not a shortcut
NVIDIA’s argument for synthetic data is practical. The most valuable agent data often sits inside organizations as private workflows, customer patterns, proprietary corpora, and local domain knowledge. Those groups may want better models, but they cannot publish the raw material that makes their workflows useful.
Synthetic data can preserve useful patterns without exposing the underlying records. It can also create local test populations, unusual edge cases, and structured workflows that would be hard or risky to collect directly.
But synthetic data introduces its own work. Someone still has to document what was generated, what was grounded in real sources, what was reviewed, and what the data is meant to test. A synthetic persona dataset can help evaluate regional or occupational fit, but it can also bake in assumptions if local experts cannot inspect and correct it.