Large Language Models News
OpenAI launches GPT-5.6 with Sol, Terra, and Luna
OpenAI launched GPT-5.6 as three models for ChatGPT Work, Codex, and the API, adding Programmatic Tool Calling, subagents, pricing, and a new system card.

By The AI Feed Desk
RuBench tests coding agents on native Russian repository tasks
RuBench adds 25 repository-level coding-agent tasks written natively in Russian, with withheld regression tests and product-agent runs.
By The AI Feed Desk
NVIDIA says harness tuning lifts Nemotron 3 Ultra in LangChain agents
NVIDIA says tuning the LangChain Deep Agents harness for Nemotron 3 Ultra improved open-stack agent performance without retraining the model.
By The AI Feed Desk
SpaceXAI launches Grok 4.5 for coding and agent work
SpaceXAI launched Grok 4.5 with coding benchmarks, $2 input and $6 output token pricing, and availability in Grok Build, Cursor, and its API console.
By The AI Feed Desk
OpenAI launches GPT-Live for full-duplex ChatGPT Voice
OpenAI is rolling out GPT-Live, a full-duplex voice model family that can listen, speak, and delegate harder work in the background.
By The AI Feed Desk
OpenAI retracts SWE-Bench Pro recommendation after benchmark audit
OpenAI audited SWE-Bench Pro and now estimates that roughly 30% of its tasks are broken, weakening a key coding-agent evaluation.
By The AI Feed Desk
Harvey LAB-AA shows legal agents still miss most complete deliverables
Artificial Analysis launched Harvey LAB-AA, a legal-agent benchmark where the top model fully passes only 14.2% of real-world legal tasks.
By The AI Feed Desk
DeepSeek legacy API model names hit a July 24 deadline
DeepSeek says the legacy `deepseek-chat` and `deepseek-reasoner` API model names will be discontinued on July 24, pushing developers to explicit V4 model IDs.
By The AI Feed Desk
AutomationBench-AA shows agents still break business guardrails
Artificial Analysis and Zapier launched AutomationBench-AA, a SaaS-agent benchmark that scores completed objectives only when business guardrails stay intact.
By The AI Feed Desk
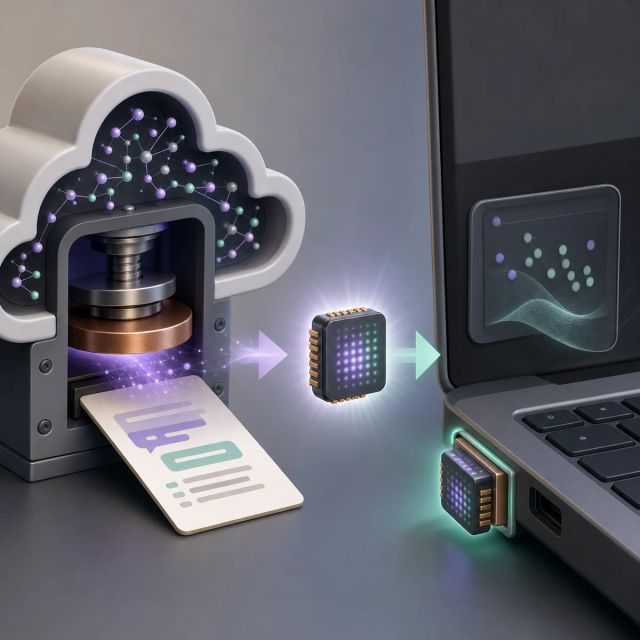
Program-as-Weights turns fuzzy functions into local adapters
A new arXiv paper proposes compiling natural-language fuzzy functions into small local adapters, shifting some LLM work from repeated API calls to reusable artifacts.
By The AI Feed Desk
Hugging Face Kernels adds trusted native-code rails
Hugging Face updated Kernels with trusted publishers, signatures, reproducible builds, and provenance checks for optimized native code on the Hub.
By The AI Feed Desk
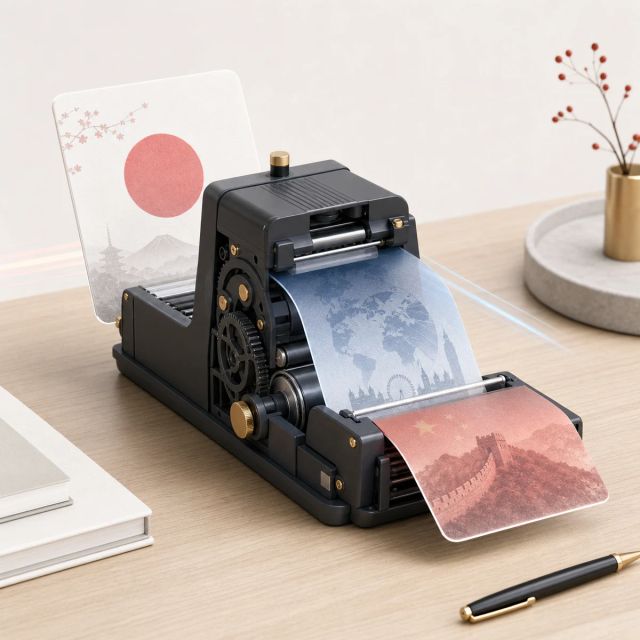
Sakana launches Namazu-powered translation in Sakana Chat
Sakana Translate adds Japanese, English, and Chinese translation to Sakana Chat, using the Namazu model series for translate, proofread, and Q&A modes.
By The AI Feed Desk
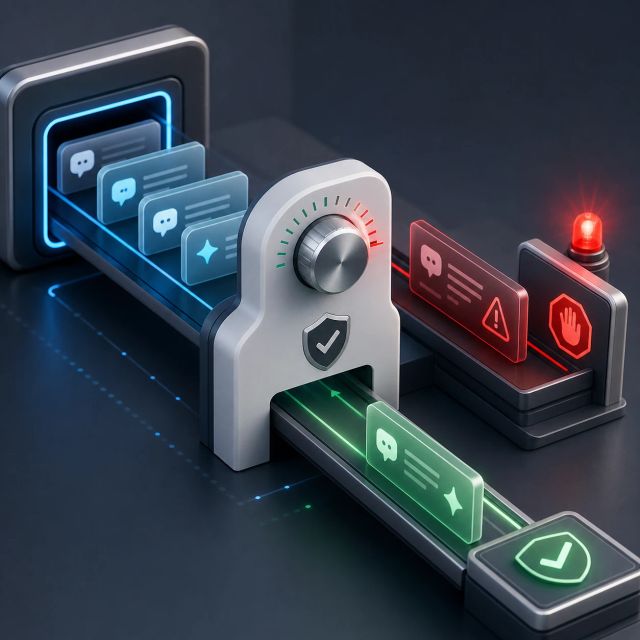
Online safety monitoring paper tests calibrated verifier alarms
A new arXiv paper studies LLM safety monitoring with an external verifier signal, calibrated risk threshold, and real-time alarm decision.
By The AI Feed Desk
LACUNA asks whether LLM unlearning reaches the weights
The LACUNA testbed evaluates whether LLM unlearning methods target the parameters that stored synthetic PII, not only whether outputs stop revealing it.
By The AI Feed Desk
GitHub Models gets a July 30 shutdown date
GitHub will fully retire GitHub Models on July 30, ending the playground, model catalog, inference API, and BYOK endpoints for all customers after two July brownouts.
By The AI Feed Desk
Metacognition-Bench tests whether models notice their own mistakes
Metacognition-Bench measures whether language models detect tempting wrong reasoning paths, pairing trap-rate evaluation with adapters that flag likely free-form errors.
By The AI Feed Desk
BaseRT makes Apple Silicon LLM speed a runtime-design question
BaseRT's paper and release argue that native Metal kernels, unified-memory-aware layout, and custom dispatch can raise local LLM throughput on Apple Silicon.
By The AI Feed Desk