AI infrastructure
Anthropic's $11.6 billion Akamai deal depends on cloud delivery
Anthropic has committed $11.6 billion for Akamai cloud capacity over seven years. The filing ties payment to delivery and sets out a staged stock warrant.

By The AI Feed Desk
NVIDIA agrees to buy Hugging Face for $12.93 billion
NVIDIA says Hugging Face will remain open after the $12.93 billion acquisition, putting platform neutrality at the center of the open-model deal.
By The AI Feed Desk
OpenAI posts first Jalapeno inference-chip benchmarks
OpenAI says its Jalapeno inference chip delivered better performance per watt and lower latency across public model workloads, with deployment planned by year end.
By The AI Feed Desk
AWS and NVIDIA plan 2 million more GPUs for agentic AI
AWS and NVIDIA say they will deploy 2 million additional NVIDIA GPUs across AWS in 2027-2028 and deepen the stack around agents, robotics, open models, and government AI.
By The AI Feed Desk
OpenAI publishes first Jalapeno inference chip results
OpenAI says Jalapeno, its first custom inference chip, delivered higher work per watt and lower latency in public-model tests and is planned for deployment by year-end.
By The AI Feed Desk
NVIDIA extends Vera Rubin with Groq 3 LPX for agentic inference
NVIDIA says Groq 3 LPX is in full production as a Vera Rubin decode accelerator, shifting agent infrastructure toward rack-scale token generation economics.
By The AI Feed Desk
Firebird opens NVIDIA-backed AI factory in Armenia
Firebird opened an NVIDIA-backed AI factory in Armenia and plans more than 70,000 Rubin and Blackwell GPUs with 300 MW of capacity by 2027.
By The AI Feed Desk
Hugging Face shows loop-owning training for coding agents
Hugging Face demonstrated a TRL and OpenEnv workflow that trains on the tokens produced by a real OpenCode agent loop in remote sandboxes.
By The AI Feed Desk
Hugging Face GPU management piece says idle accelerators are the next AI constraint
A Hugging Face community article argues that enterprise AI economics are shifting from model access to GPU utilization, scheduling, and workload orchestration.
By The AI Feed Desk
OpenAI cuts GPT-5.6 Luna and Terra prices
OpenAI cut GPT-5.6 Luna pricing by 80%, Terra pricing by 20%, and added a faster Sol API mode for latency-sensitive work.
By The AI Feed Desk
NVIDIA gives Safe Superintelligence a 10x compute path
NVIDIA and Safe Superintelligence announced a long-term partnership that includes NVIDIA investment and access to Vera Rubin systems.
By The AI Feed Desk
NVIDIA frames Vera Rubin around agentic post-training economics
NVIDIA says Vera Rubin is built for continuous post-training loops and can train the largest models with one-fourth the GPUs of Blackwell.
By The AI Feed Desk
NVIDIA uses Japan to package physical AI as a full-stack ecosystem
NVIDIA's July 15 Japan ecosystem update ties RTX Spark, robotics, manufacturing, and local partners into a physical AI stack.
By The AI Feed Desk
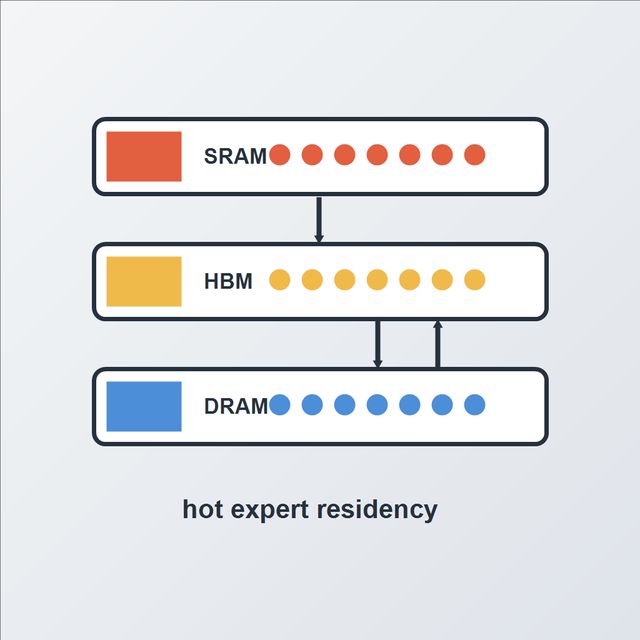
HCRMap targets hot-expert bottlenecks in MoE inference
A July 13 paper proposes HCRMap, a pressure-aware residency system for hot MoE experts across 3.5D chiplet memory tiers.
By The AI Feed Desk
Hugging Face cloud handoffs turn model pages into deployment paths
AWS and SkyPilot integrations show Hugging Face model pages becoming handoffs into managed SageMaker workflows and portable multi-cloud GPU jobs.
By The AI Feed Desk
NVIDIA frames U.S. AI buildout as a 43-state supply chain
NVIDIA says its U.S. partner network spans 43 states and plans up to $500 billion of American-built AI infrastructure with semiconductor, system, power, and cloud partners.
By The AI Feed Desk
NVIDIA turns AI cloud capacity into a revenue-sharing model
NVIDIA's new AI cloud model pairs revenue sharing with credit support, giving emerging cloud providers a way to finance AI factories while tying NVIDIA to downstream token demand.
By The AI Feed Desk