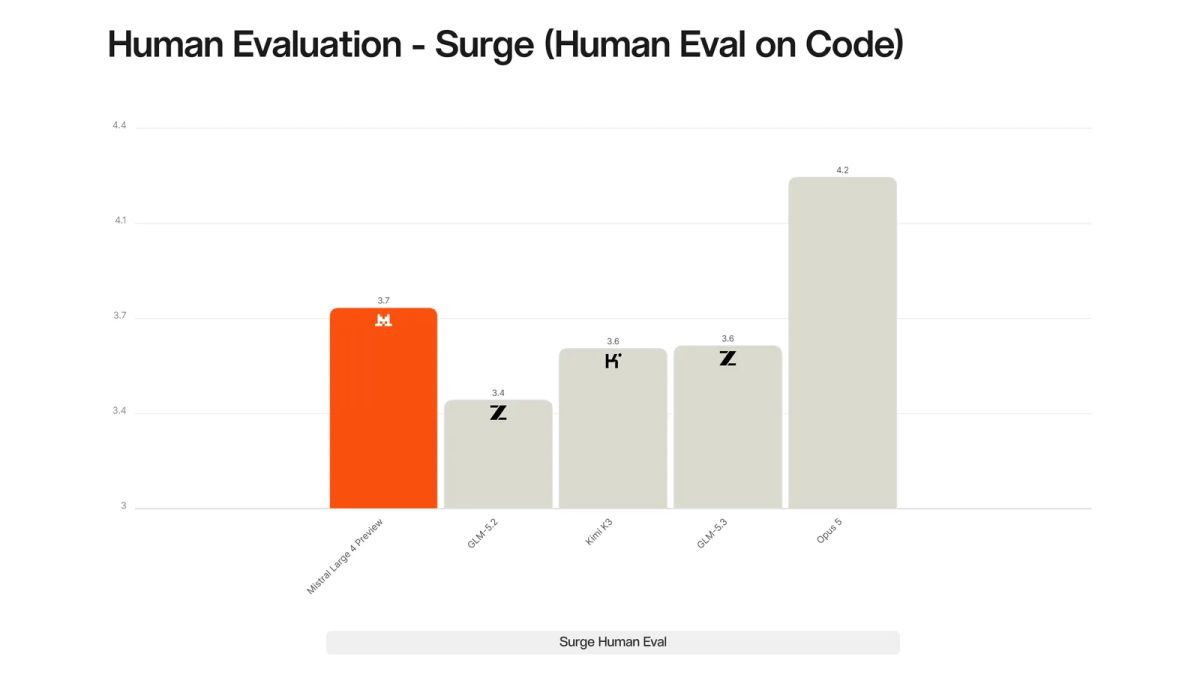
Bar chart of coding quality ratings with Mistral Large 4 Preview below Claude Opus 5 and above GLM-5.2, Kimi K3 and GLM-5.3
+ AI News

Mistral Large 4 is a 1T multimodal model aimed at closed and open rivals

Mistral Large 4 opens in API preview ahead of a planned weight release. Its size and benchmark claims give builders separate questions about capability and control.

Mistral launched Large 4 on October 6 as a multimodal flagship aimed at American closed models and Chinese open-weight rivals. Nicknamed Le Chonk, it has one trillion parameters. Builders can try a public API preview now, while the promised weight release remains ahead.

TechCrunch reports that access initially runs through a guarded endpoint. Mistral VP Science Pierre Stock told the outlet that the company plans to release weights after three weeks of safety testing with trusted partners and governments. He named cybersecurity, finance and chip design as optimized uses.

A large model with a staged release

Mistral’s announcement specifies 49 billion active parameters and targets the end of October for weights. It says training used 3,800 Nvidia Grace Blackwell GPUs in its European datacenters, which also serve the preview. TechCrunch quotes Stock’s rounded figure of 4,000 GPUs.

The deployment pitch is control. TechCrunch describes Mistral’s target audience as enterprises and institutions concerned about security and access to models. Stock argues that open weights make auditing easier. For teams choosing a provider, today’s endpoint access and the planned weight release are separate stages of that offer.

The published comparisons narrow the performance claim

TechCrunch describes benchmark results as pending. Mistral’s release page now includes reported evaluations, so readers have more evidence to assess than that report alone provides.

The lead chart shows a blind coding-quality evaluation Mistral ran with Surge AI. Large 4 scored 3.74 on a five-point scale, behind Claude Opus 5 at 4.22 and ahead of the tested Kimi and GLM models. Mistral also reports a visual-grounding score of 42% on Dense 200 against GPT-6 Astra’s 41%.

These are comparisons published by Mistral. They support a narrower claim of competitiveness on selected tasks than a general lead over closed and open rivals.

Sources

The AI Feed Desk

The AI Feed Desk

Editorial desk

The AI Feed Desk tracks AI provider updates, model releases, agent tooling, and enterprise adoption, turning fast-moving announcements into source-linked context for builders and operators.

Noticed a typo, incorrect information, or translation error?

Tell us so we can fix it.

Help Improve This Article

Related Articles

A document page is segmented into blocks that flow into a retrieval pipeline

Mistral OCR 4 adds structured document extraction for enterprise RAG

Mistral OCR 4 returns bounding boxes, block types, confidence scores, and 170-language coverage so document AI can feed retrieval, citations, and agent workflows.

The AI Feed Desk

By The AI Feed Desk

Beam lettering beside overlapping white rings and dots on a dark green background

Reflection debuts Beam, a 501B open-weight model aimed at rivaling Chinese models

Reflection previews Beam with 23B active parameters and an Apache 2.0 release planned for October. Its lower-compute claim leaves serving costs to be tested.

The AI Feed Desk

By The AI Feed Desk

An evaluator point inside a model development box connects to an external report; illustration

Anthropic and Accenture put $2 billion behind embedded model evaluation

Anthropic and Accenture each plan to invest at least $1 billion in embedded AI evaluation capacity, while acknowledging that access, reporting, and funding standards do not exist yet.

The AI Feed Desk

By The AI Feed Desk

Illustration of a training workbook and software project tile beside Claude Frontier Academy funding and engineer targets

Anthropic commits $100 million to train 10,000 engineers at Claude Frontier Academy

Claude Frontier Academy pairs practical assessments with a 12-week workplace project. Anthropic aims to train 10,000 engineers by the end of 2027.

The AI Feed Desk

By The AI Feed Desk

Prompt cards pass through a policy checkpoint before entering a model core

Anthropic adds Inference hooks for Claude Enterprise prompt control

Anthropic put Inference hooks into beta for Claude Enterprise, letting governed prompts pass through an organization's security server before Claude processes them.

The AI Feed Desk

By The AI Feed Desk