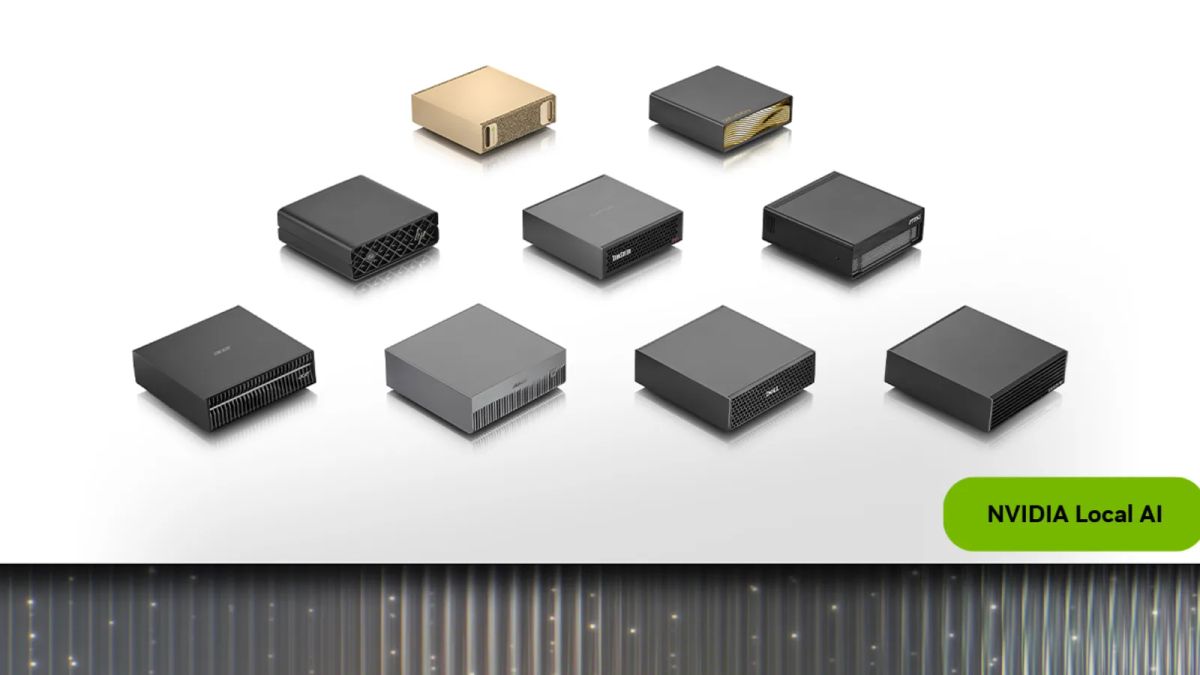
Nine compact desktop systems arranged on a white background above a green NVIDIA Local AI label
+ NVIDIA AI News

Nvidia's DGX Spark gets a 64GB unified memory version this month

Nvidia's 64GB DGX Spark arrives October 23 from partner manufacturers, starting at $4,999. Its 100-billion-parameter claim needs a closer memory-budget check.

Nvidia says a 64GB unified memory version of DGX Spark will arrive on October 23, starting at $4,999. Acer, ASUS, Dell, Gigabyte, HP and MSI will sell the configuration. It gives builders a smaller-memory option alongside the existing 128GB model for running AI models and agents locally.

In its October 2 announcement, Nvidia says the partner-only configuration retains the GB10 Grace Blackwell Superchip, DGX OS and the full Nvidia AI software stack. The company claims support for models with up to 100 billion parameters on one system.

What the hardware and software include

DGX Spark has a built-in ConnectX-7 network interface. Two 64GB systems can connect directly through a QSFP cable over a 200 GbE network. Nvidia says that gives the cluster 128GB of pooled memory and support for models with up to 200 billion parameters.

Nvidia Sync Cluster Assistant detects connected systems, validates their configuration and sets up the ConnectX-7 network. In Nvidia’s Qwen3.8 27B test, two 64GB systems delivered up to 1.7 times the performance of one system. That result applies to the company’s reported test, so buyers should check their own model and workload before budgeting for the same gain.

The software stack supports Nvidia Agent Toolkit, Nemotron models and CUDA-enabled runtimes including Ollama, vLLM and PyTorch. Nvidia also lists llama.cpp and LM Studio as supported inference options.

At the end of October, Nvidia plans to release Sync Model Launcher. It will download and launch Qwen3.8 27B on one Spark or a cluster, make the model accessible from a laptop and configure OpenCode to use it for coding in a browser.

Sources

The AI Feed Desk

The AI Feed Desk

Editorial desk

The AI Feed Desk tracks AI provider updates, model releases, agent tooling, and enterprise adoption, turning fast-moving announcements into source-linked context for builders and operators.

Noticed a typo, incorrect information, or translation error?

Tell us so we can fix it.

Help Improve This Article

Related Articles

Open model weights and cybersecurity tools sit between two policy paths labeled access, testing, chips, and safeguards

NVIDIA and Anthropic split over open-weight AI safety

NVIDIA launched the Open Secure AI Alliance while Anthropic argued against blanket open-weight bans and for targeted AI safety controls.

The AI Feed Desk

By The AI Feed Desk

A green-accented compute pillar supports an open model library used by developers

NVIDIA agrees to buy Hugging Face for $12.93 billion

NVIDIA says Hugging Face will remain open after the $12.93 billion acquisition, putting platform neutrality at the center of the open-model deal.

The AI Feed Desk

By The AI Feed Desk

A green open-model core runs inside a sealed air-gapped compute chamber

NVIDIA and Palantir put Nemotron open models inside air-gapped government AI

NVIDIA says Palantir is using Nemotron open models in isolated environments for U.S. government agencies and critical infrastructure operators.

The AI Feed Desk

By The AI Feed Desk

Editorial illustration of a local text model generating many tokens in parallel on a GPU

Google releases DiffusionGemma for faster local text generation

Google's DiffusionGemma is an experimental open text-diffusion model that generates blocks of text in parallel for lower-latency local workflows.

The AI Feed Desk

By The AI Feed Desk

An AI server rack connects to a warm closed-loop liquid cooling system and dry cooler

NVIDIA says 45 C liquid cooling can reshape AI factory design

NVIDIA says Rubin-generation AI infrastructure can run with 45 C coolant in closed-loop liquid-cooled AI factories, reducing cooling energy and water dependence.

The AI Feed Desk

By The AI Feed Desk