Open models
Nvidia's DGX Spark gets a 64GB unified memory version this month
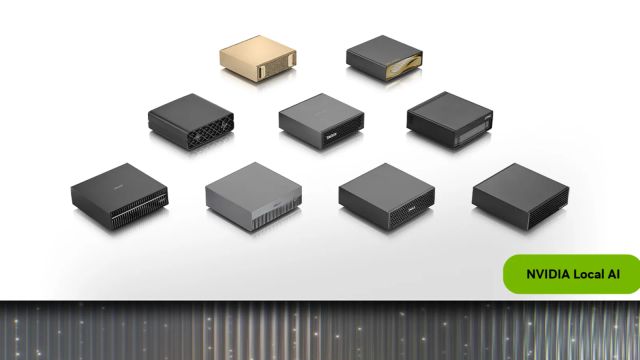
Nvidia's 64GB DGX Spark arrives October 23 from partner manufacturers, starting at $4,999. Its 100-billion-parameter claim needs a closer memory-budget check.

By The AI Feed Desk
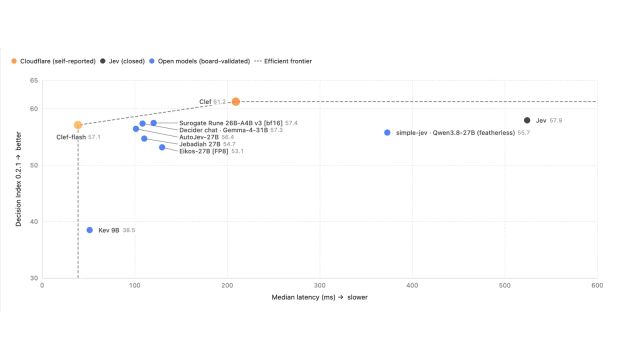
Amazon and Cloudflare release open decision models as the Jev clones multiply
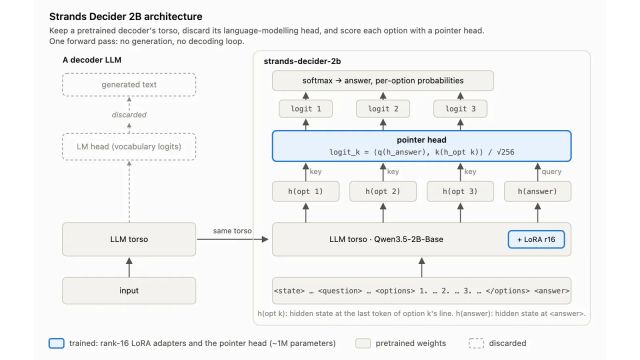
AWS releases Strands Decider 2B. Cloudflare adds Clef and Clef-flash, with open weights and hands-on fine-tuning. Task scores show where speed costs accuracy.
By The AI Feed Desk
OpenAI's Decisions API and the Jev clones racing to match it
OpenAI previews a Jev-style decision API. Jeff, Jeeves and Jevstiller offer different local approaches, with trade-offs in speed, reasoning and agreement.
By The AI Feed Desk
Holo4's desktop results vary sharply by model size
H Company released two open-weight Holo4 agents for computer use. Its own OSWorld 2.0 results put the 27B model at 61.7% and the 35B-A3B model at 30.9%.
By The AI Feed Desk
NVIDIA agrees to buy Hugging Face for $12.93 billion
NVIDIA says Hugging Face will remain open after the $12.93 billion acquisition, putting platform neutrality at the center of the open-model deal.
By The AI Feed Desk
IBM releases Granite 4.2 open reasoning models for agents
IBM's Granite 4.2 family adds reasoning, tool use, agentic reinforcement learning, quantized variants, and Apache 2.0 weights for enterprise deployment.
By The AI Feed Desk
Hugging Face says open-model adoption is not attention
Hugging Face's summer 2026 open-model report says model repositories grew quickly, while actual downloads concentrated in a small infrastructure layer.
By The AI Feed Desk
NVIDIA and Anthropic split over open-weight AI safety
NVIDIA launched the Open Secure AI Alliance while Anthropic argued against blanket open-weight bans and for targeted AI safety controls.
By The AI Feed Desk
Nunchaku 4-bit diffusion inference lands in Diffusers
Hugging Face says current Diffusers can load Nunchaku checkpoints with from_pretrained, bringing 4-bit diffusion inference into a familiar workflow.
By The AI Feed Desk
Microsoft makes the policy case for open-weight AI
Microsoft's July 24 policy page argues that open-weight AI can expand access, competition, security, and U.S. AI leadership.
By The AI Feed Desk
Hugging Face says an autonomous agent breached production infrastructure
Hugging Face disclosed a July 2026 production incident it says was driven by an autonomous AI agent system and recommends token rotation.
By The AI Feed Desk
Moonshot launches Kimi K3 as an open 2.8T model
Moonshot's Kimi K3 pairs a 2.8T-parameter model, 1M-token context, API access, and a promised July 27 weight release.
By The AI Feed Desk
Hugging Face and vLLM bring native-speed serving to Transformers model definitions
Hugging Face and vLLM introduced a backend that can run compatible Transformers model definitions at native vLLM speed through runtime graph analysis and rewrites.
By The AI Feed Desk
NVIDIA says harness tuning lifts Nemotron 3 Ultra in LangChain agents
NVIDIA says tuning the LangChain Deep Agents harness for Nemotron 3 Ultra improved open-stack agent performance without retraining the model.
By The AI Feed Desk
BaseRT makes Apple Silicon LLM speed a runtime-design question
BaseRT's paper and release argue that native Metal kernels, unified-memory-aware layout, and custom dispatch can raise local LLM throughput on Apple Silicon.
By The AI Feed Desk
Hugging Face and Cerebras make open voice AI a latency problem
A Hugging Face and Cerebras speech-to-speech demo uses Parakeet, Gemma 4, Cerebras inference, and Qwen3TTS to show where voice AI latency actually lives.
By The AI Feed Desk
Hugging Face and Every Eval Ever make model-card scores more inspectable
Community Evals and Every Eval Ever now connect model-page benchmark scores to structured provenance records.
By The AI Feed Desk