Model evaluation
OpenAI retracts SWE-Bench Pro recommendation after benchmark audit
OpenAI audited SWE-Bench Pro and now estimates that roughly 30% of its tasks are broken, weakening a key coding-agent evaluation.

By The AI Feed Desk
Harvey LAB-AA shows legal agents still miss most complete deliverables
Artificial Analysis launched Harvey LAB-AA, a legal-agent benchmark where the top model fully passes only 14.2% of real-world legal tasks.
By The AI Feed Desk
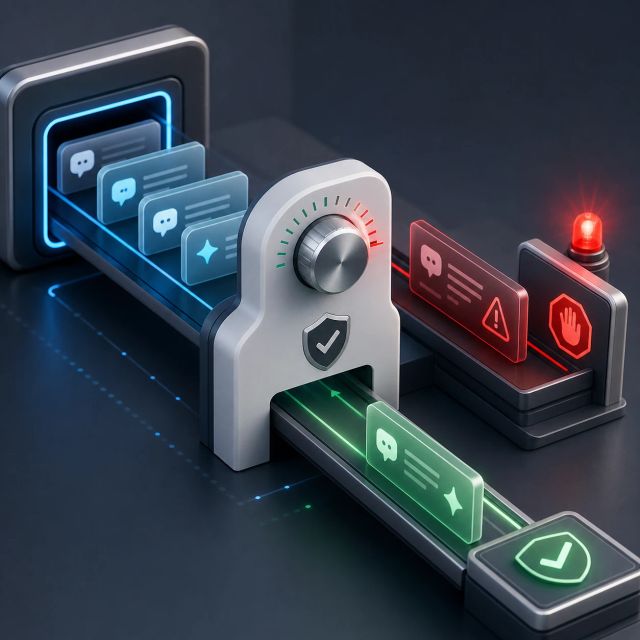
Online safety monitoring paper tests calibrated verifier alarms
A new arXiv paper studies LLM safety monitoring with an external verifier signal, calibrated risk threshold, and real-time alarm decision.
By The AI Feed Desk
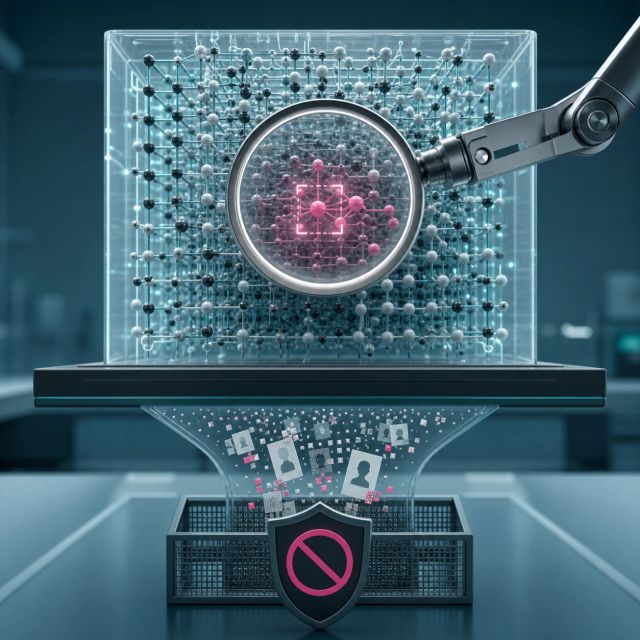
LACUNA asks whether LLM unlearning reaches the weights
The LACUNA testbed evaluates whether LLM unlearning methods target the parameters that stored synthetic PII, not only whether outputs stop revealing it.
By The AI Feed Desk
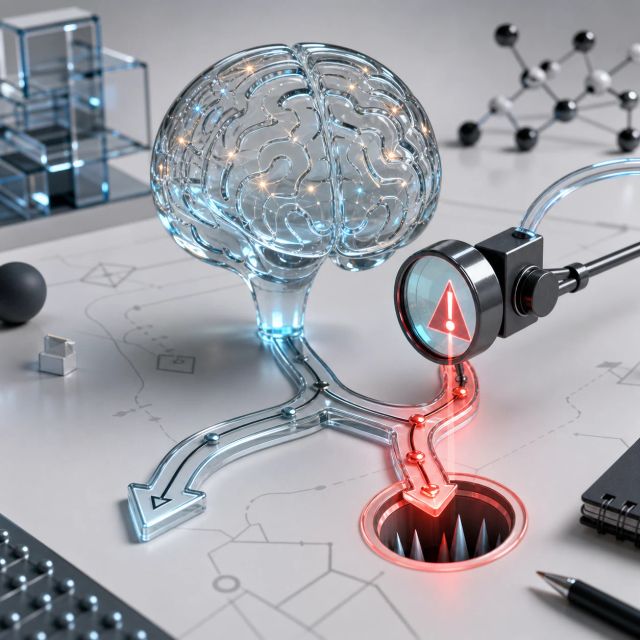
Metacognition-Bench tests whether models notice their own mistakes
Metacognition-Bench measures whether language models detect tempting wrong reasoning paths, pairing trap-rate evaluation with adapters that flag likely free-form errors.
By The AI Feed Desk
Persistent coding agents create a distributed attack surface
A new arXiv paper argues that persistent coding agents can hide malicious behavior across multiple pull requests, making monitor design a stateful problem.
By The AI Feed Desk
Hugging Face and Every Eval Ever make model-card scores more inspectable
Community Evals and Every Eval Ever now connect model-page benchmark scores to structured provenance records.
By The AI Feed Desk
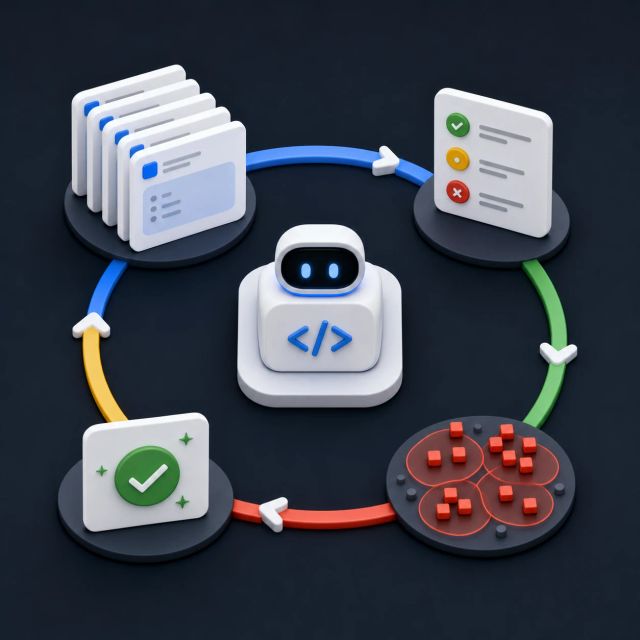
Google gives coding agents an eval flywheel instead of another prompt tweak
Google's new quality-flywheel skill lets coding agents run structured agent evaluations with independent grading and production-trace loops.
By The AI Feed Desk
OpenAI's GeneBench-Pro makes biology benchmarks about judgment
GeneBench-Pro tests whether AI agents can handle ambiguous computational-biology analysis, not just clean benchmark questions.
By The AI Feed Desk
Cognition's FrontierCode asks whether AI code would survive review
FrontierCode evaluates coding agents on mergeability, code quality, scope, tests, and maintainer judgment instead of only functional correctness.
By The AI Feed Desk
AA-Briefcase tests agents on messy business work
Artificial Analysis' AA-Briefcase benchmark evaluates models on multi-week knowledge-work projects with documents, email, Slack data, deliverables, and graded analysis quality.
By The AI Feed Desk
Patronus raises $50M to build simulated worlds for agent training
Patronus AI paired a $50M Series B with a Digital World Model preview, betting that agents need realistic simulated environments before they can be trusted at work.
By The AI Feed Desk
OpenAI's rare-disease study makes old genome cases worth reopening
OpenAI says o3 Deep Research helped experts reanalyze 376 previously unsolved rare-disease cases and establish 18 diagnoses after clinical review.
By The AI Feed Desk