Inference
OpenAI posts first Jalapeno inference-chip benchmarks
OpenAI says its Jalapeno inference chip delivered better performance per watt and lower latency across public model workloads, with deployment planned by year end.

By The AI Feed Desk
MLCommons introduces an end-to-end RAG inference benchmark
MLCommons introduced an end-to-end RAG inference benchmark that measures document ingestion, vector search, and multi-hop answer generation together.
By The AI Feed Desk
OpenAI publishes first Jalapeno inference chip results
OpenAI says Jalapeno, its first custom inference chip, delivered higher work per watt and lower latency in public-model tests and is planned for deployment by year-end.
By The AI Feed Desk
NVIDIA extends Vera Rubin with Groq 3 LPX for agentic inference
NVIDIA says Groq 3 LPX is in full production as a Vera Rubin decode accelerator, shifting agent infrastructure toward rack-scale token generation economics.
By The AI Feed Desk
Hugging Face adds Baseten as an Inference Provider
Hugging Face added Baseten as an Inference Provider, giving developers routed serverless access to open-weight text and chat models from Hub model pages and SDKs.
By The AI Feed Desk
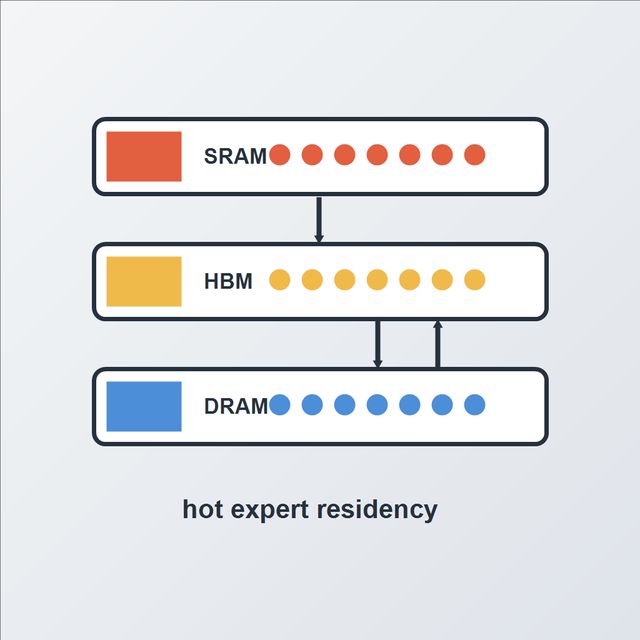
HCRMap targets hot-expert bottlenecks in MoE inference
A July 13 paper proposes HCRMap, a pressure-aware residency system for hot MoE experts across 3.5D chiplet memory tiers.
By The AI Feed Desk
Hugging Face and vLLM bring native-speed serving to Transformers model definitions
Hugging Face and vLLM introduced a backend that can run compatible Transformers model definitions at native vLLM speed through runtime graph analysis and rewrites.
By The AI Feed Desk
BaseRT makes Apple Silicon LLM speed a runtime-design question
BaseRT's paper and release argue that native Metal kernels, unified-memory-aware layout, and custom dispatch can raise local LLM throughput on Apple Silicon.
By The AI Feed Desk
NVIDIA turns AI cloud capacity into a revenue-sharing model
NVIDIA's new AI cloud model pairs revenue sharing with credit support, giving emerging cloud providers a way to finance AI factories while tying NVIDIA to downstream token demand.
By The AI Feed Desk
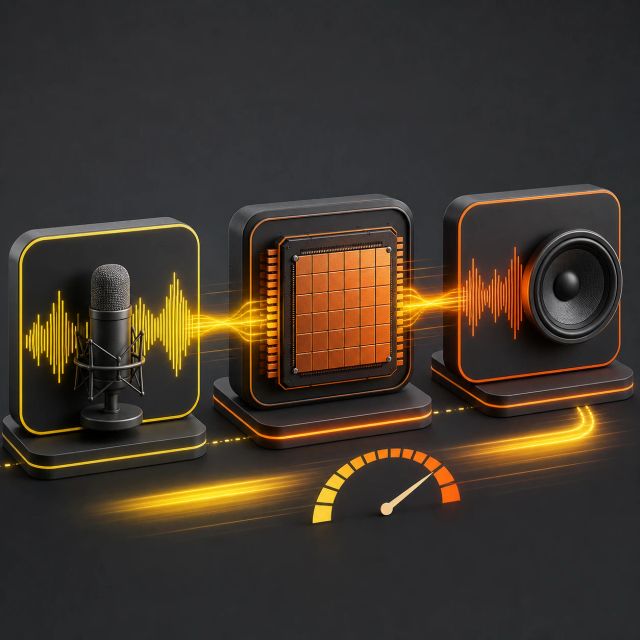
Hugging Face and Cerebras make open voice AI a latency problem
A Hugging Face and Cerebras speech-to-speech demo uses Parakeet, Gemma 4, Cerebras inference, and Qwen3TTS to show where voice AI latency actually lives.
By The AI Feed Desk
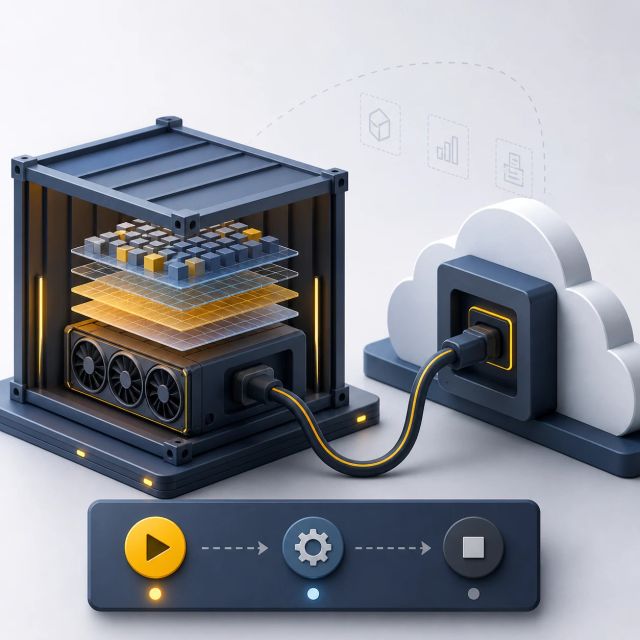
Hugging Face makes vLLM serving a one-command Jobs workflow
HF Jobs can now spin up a private OpenAI-compatible vLLM endpoint for tests, evals, and batch generation without provisioning servers or managing Kubernetes.
By The AI Feed Desk
Qualcomm agrees to acquire Modular for AI software portability
Qualcomm's Modular deal puts compiler and runtime portability at the center of its edge-to-cloud AI infrastructure push.
By The AI Feed Desk
OpenAI and Broadcom unveil Jalapeno inference chip
OpenAI's first Intelligence Processor moves its compute strategy deeper into custom inference hardware, with Broadcom and Celestica helping turn the chip into a deployable platform.
By The AI Feed Desk
NVIDIA says Blackwell leads the first AgentPerf benchmark
NVIDIA says GB300 NVL72 runs up to 20x more agents per megawatt than H200 on AgentPerf, a new benchmark for agentic inference.
By The AI Feed Desk
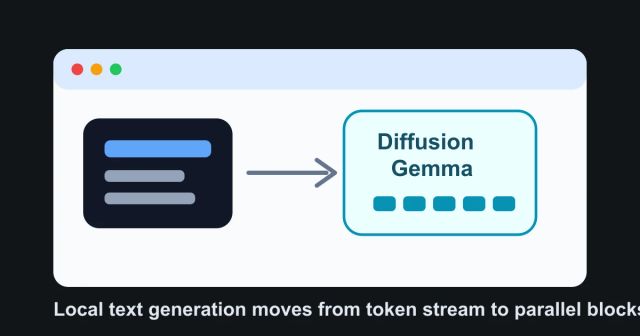
Google releases DiffusionGemma for faster local text generation
Google's DiffusionGemma is an experimental open text-diffusion model that generates blocks of text in parallel for lower-latency local workflows.
By The AI Feed Desk
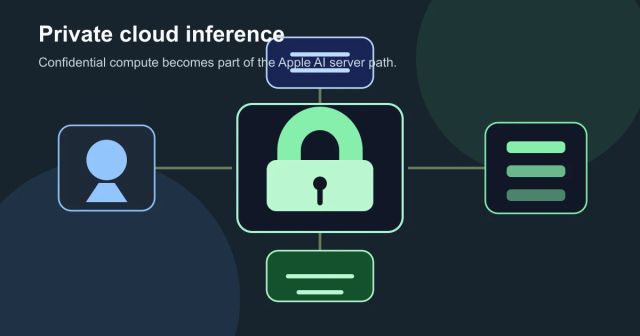
NVIDIA says Apple Private Cloud Compute will use Blackwell GPUs on Google Cloud
NVIDIA says Apple Private Cloud Compute is expanding to Google Cloud with Blackwell GPUs and Confidential Computing for server-side Apple Intelligence inference.
By The AI Feed Desk