NVIDIA
NVIDIA says harness tuning lifts Nemotron 3 Ultra in LangChain agents
NVIDIA says tuning the LangChain Deep Agents harness for Nemotron 3 Ultra improved open-stack agent performance without retraining the model.

By The AI Feed Desk
NVIDIA frames U.S. AI buildout as a 43-state supply chain
NVIDIA says its U.S. partner network spans 43 states and plans up to $500 billion of American-built AI infrastructure with semiconductor, system, power, and cloud partners.
By The AI Feed Desk
NVIDIA turns AI cloud capacity into a revenue-sharing model
NVIDIA's new AI cloud model pairs revenue sharing with credit support, giving emerging cloud providers a way to finance AI factories while tying NVIDIA to downstream token demand.
By The AI Feed Desk
NVIDIA and Palantir put Nemotron open models inside air-gapped government AI
NVIDIA says Palantir is using Nemotron open models in isolated environments for U.S. government agencies and critical infrastructure operators.
By The AI Feed Desk
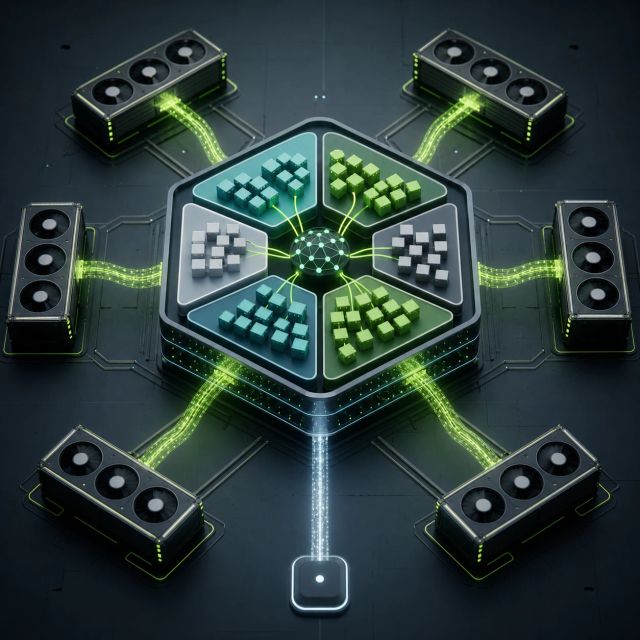
NVIDIA NeMo AutoModel makes MoE fine-tuning a one-import upgrade
NVIDIA's Hugging Face article shows NeMo AutoModel wrapping expert parallelism and custom kernels behind the familiar Transformers loading path for MoE fine-tuning.
By The AI Feed Desk
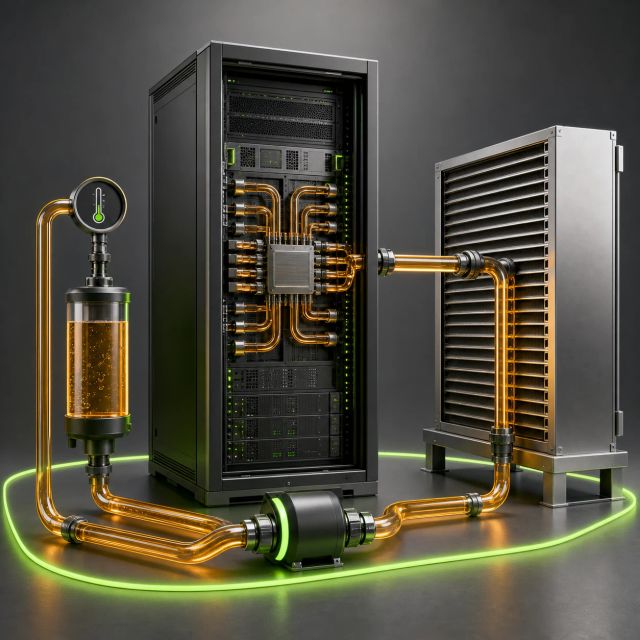
NVIDIA says 45 C liquid cooling can reshape AI factory design
NVIDIA says Rubin-generation AI infrastructure can run with 45 C coolant in closed-loop liquid-cooled AI factories, reducing cooling energy and water dependence.
By The AI Feed Desk
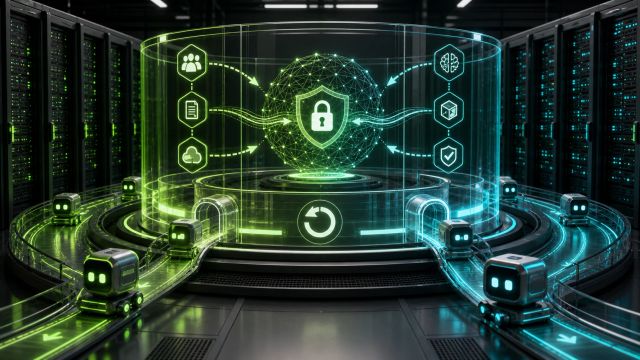
NVIDIA and HPE package agent infrastructure as a private-cloud control plane
HPE AI Factory with NVIDIA is adding Vera CPU, NVIDIA Agent Toolkit, confidential computing, local agent registration, and rollback controls.
By The AI Feed Desk
NVIDIA says Blackwell swept MLPerf Training 6.0
NVIDIA says Blackwell delivered the fastest time to train on all seven MLPerf Training 6.0 benchmarks, including large-scale DeepSeek-V3 and Llama workloads.
By The AI Feed Desk
NVIDIA says Blackwell leads the first AgentPerf benchmark
NVIDIA says GB300 NVL72 runs up to 20x more agents per megawatt than H200 on AgentPerf, a new benchmark for agentic inference.
By The AI Feed Desk
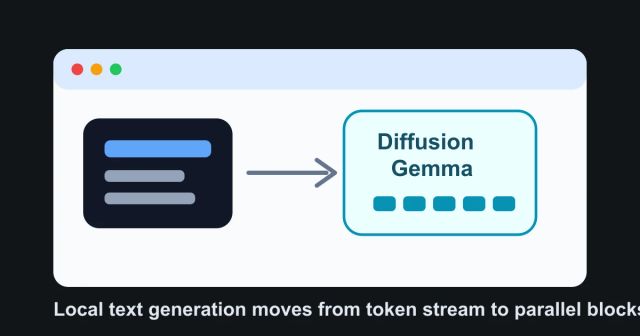
Google releases DiffusionGemma for faster local text generation
Google's DiffusionGemma is an experimental open text-diffusion model that generates blocks of text in parallel for lower-latency local workflows.
By The AI Feed Desk
NVIDIA says Apple Private Cloud Compute will use Blackwell GPUs on Google Cloud
NVIDIA says Apple Private Cloud Compute is expanding to Google Cloud with Blackwell GPUs and Confidential Computing for server-side Apple Intelligence inference.
By The AI Feed Desk
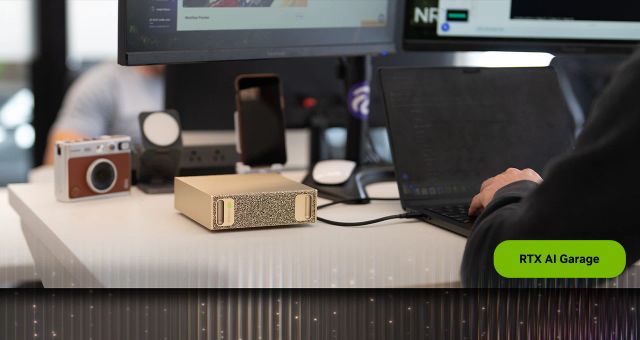
NVIDIA announces RTX Spark PCs for local AI agents
RTX Spark puts 1 petaflop of AI performance and up to 128GB of unified memory into Windows PCs designed for local agents.
By The AI Feed Desk